Willa Lorenz · 29 September 2026
Navigating Annotation Evolution in Dynamic Hosting Environments
Dynamic hosting environments continue to reshape how annotation systems manage data labels and metadata across shifting server infrastructures, containerized deployments, and multi-cloud setups, where resources scale or migrate without warning and teams must maintain consistency in labeling pipelines that support machine learning models or document workflows.
Core Components of Annotation Systems
Annotation frameworks rely on structured schemas that assign categories, bounding boxes, or semantic tags to datasets, and these schemas must adapt when hosting providers alter their underlying architectures because changes in latency, storage formats, or access controls can break existing label storage methods. Researchers at various institutions have tracked how versioned annotation databases handle live migrations, and data shows that systems using distributed ledgers or immutable audit trails preserve label integrity better during such transitions.
Take one research team that monitored a financial services platform moving from on-premise servers to elastic cloud instances, where annotation tools updated their metadata references automatically through API hooks that detected host changes in real time, and this approach reduced label drift by measurable margins according to internal logs shared in technical reports.
Adaptation Patterns During Infrastructure Shifts
Hosting environments often introduce variables such as new virtualization layers or regional data residency rules, which force annotation platforms to evolve their synchronization protocols so that labels remain attached to the correct data objects even after workloads relocate across availability zones. Evidence from industry monitoring indicates that organizations implementing event-driven triggers for annotation updates achieve smoother continuity compared with batch-based reconciliation methods that run on fixed schedules.
What's interesting is how September 2026 brings scheduled enhancements to several major cloud orchestration standards that will require annotation tools to support finer-grained permission models for label access, and those preparing early have begun testing compatibility layers that map legacy schemas onto the incoming requirements without data loss.
Technical Mechanisms Supporting Evolution
Modern annotation evolution draws on container orchestration features that allow annotation services to redeploy alongside data pipelines, while maintaining connections to persistent label stores through abstracted interfaces rather than hardcoded endpoints, and this separation helps when hosting authorities rotate credentials or update network policies. Studies from academic sources reveal that graph-based annotation representations handle these changes more gracefully than flat file structures because relationships between labels and source files can reroute dynamically.
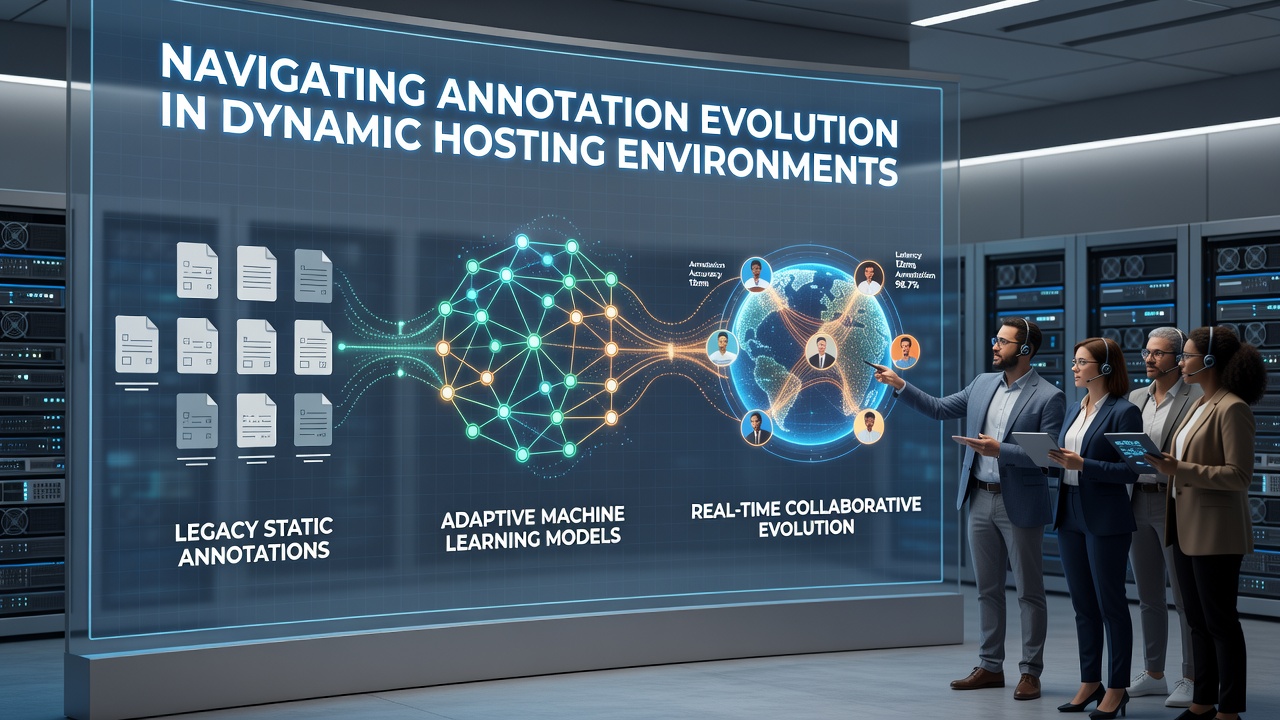
One documented case involved a healthcare analytics group that integrated annotation evolution logic into their Kubernetes operators, enabling automatic schema migrations whenever pods spun up on new host clusters, and results published in conference proceedings showed sustained query performance for labeled datasets throughout the process.
Regulatory and Standards Influences
Government bodies and standards organizations shape annotation practices in dynamic hosting by issuing guidelines on data traceability and auditability, with the National Institute of Standards and Technology outlining cloud characteristics that affect how labels must travel with datasets during provider switches, and similar guidance from Canadian research initiatives emphasizes encryption of annotation metadata to meet cross-border hosting rules.
Observers note that these frameworks encourage annotation systems to embed provenance tracking directly into their core structures so that any hosting change leaves a verifiable record, and this practice aligns with emerging requirements from trade groups focused on responsible data handling in scalable environments.
Implementation Examples Across Sectors
Retail analytics operations have adopted annotation evolution strategies that link label updates to hosting health checks, allowing systems to pause labeling tasks during detected instabilities and resume with reconciled data once new hosts stabilize, whereas academic research groups often experiment with federated annotation models that distribute label authority across multiple hosting jurisdictions to reduce single-point dependencies.
Turns out these varied approaches share a common thread in their use of standardized interchange formats that decouple annotation content from specific hosting implementations, and figures from cross-industry surveys reveal gradual adoption rates climbing as tools mature.
Conclusion
Annotation evolution in dynamic hosting environments centers on maintaining label accuracy and accessibility amid continuous infrastructure adjustments through adaptive schemas, event-driven updates, and provenance mechanisms that respond to changes without manual intervention, and ongoing developments scheduled around September 2026 will likely accelerate these capabilities further as hosting standards continue to advance.